
Uncover hidden structure in your data
We create mathematically-grounded data solutions that support scientific discovery and technical innovation. When your problem requires more than off-the-shelf tools, we develop the mathematics and software to solve it end-to-end.
Mathematically-grounded analysis
Our team of mathematicians and computer scientists solve complex data
challenges at the intersection of advanced mathematics and AI. We use
mathematical techniques to bridge technical gaps in scientific fields,
always prioritizing transparency, scalability, and interpretability.
We take a professional, test-driven approach to agile, deployable, interoperable, maintainable software through Test-Driven Development, optimized CI/CD pipelines, self-documenting API endpoints, and scalable containerized microservices. Our team fuses scientific expertise with deep knowledge of modern test-driven software engineering, microservice architecture, and scalable deployment.
We cover the complete development cycle from scientific ideation to coding to scaling to deployment.
Algorithms & TDA
Where off-the-shelf methods stall, we build the algorithm the problem actually calls for. When the structure of the data is itself the obstacle, we bring geometric and topological tools to bear.
Algorithm development & deployment
Not every problem is an AI problem. We tailor and develop custom algorithms across machine learning, optimization, and signal processing. We have particular expertise in
- supply chain logistics and planning
- drone swarms
- geospatial environmental data, routing, and planning
Our process
- Conduct needs analysis
- Expert review of literature and state-of-the-art techniques
- Create working prototype and test suite
- Write production-level code and API documentation
- Deploy solution and ongoing systems review
Algorithms & TDA
Where off-the-shelf methods stall, we build the algorithm the problem actually calls for. When the structure of the data is itself the obstacle, we bring geometric and topological tools to bear.
Topological Data Analysis
Our techniques reveal multiscale structure in data that other methods miss and generate robust descriptors that are independent of orientation or parameterization. TDA is a strong fit for high-dimensional or noisy data where traditional approaches underperform.
Our process
- Data structure analysis and dimensionality estimation
- Experimental test suite for algorithm selection
- Implement and benchmark solution against non-TDA solutions
- Deliver outcome as either Python package or Docker container with API documentation
ML & AI Systems
Get rigorous model assessment, validation, and verification services to ensure ML & AI systems meet the highest standards of reliability and trustworthiness—essential for managing risk and maintaining accountability. We provide our clients with functional software packages, documented API endpoints, and ready-to-deploy microservice containers.
Machine Learning
We apply state of the art ML techniques to hard data problems. Our approach moves beyond traditional ML to extract informative features, reduce the complexity and dimensionality of non-traditional or high-dimensional data types, and allows us to expand the utility of machine learning approaches. We specialize in reinforcement learning, active learning, and geospatial analysis.
Our process
- Data identification and exploration
- Experimental test suite for algorithm and hyperparameter selection
- Translate tuning notebooks into production-ready deployable models and packaged code
- Documented summary of results and insights
- Evaluation and further recommendations
ML & AI Systems
Get rigorous model assessment, validation, and verification services to ensure ML & AI systems meet the highest standards of reliability and trustworthiness—essential for managing risk and maintaining accountability. We provide our clients with functional software packages, documented API endpoints, and ready-to-deploy microservice containers.
Generative AI & LLMs
We develop production-ready tools enhanced by generative AI and large language models. By incorporating chatbots, RAGs, and multi-agent systems into our solutions, our clients are provided with bespoke solutions tailored to their needs.
Our process
- Build a document store, text classification, and taxonomy generation
- Define client-specified functions and trained ML models for accurate predictions
- Develop chatbots integrated with MCP and RAG
- Evaluate model and chatbot output, fine tune and benchmark
- Isolated access via sandboxed environments, on-prem or cloud deployment
- Deploy application and provide further evaluations and recommendations
Software & Data Engineering
Accelerate your R&D process and transform messy, unstructured data into clean, validated data with our hybrid approach of AI tooling and mathematically grounded analysis. We build and maintain systems that get it from prototype to production.
Data Pipelines
We design and build robust data pipelines that process real-time data, transforming raw streams into clean, analysis-ready inputs. Time-sensitive signals are captured, structured, and delivered with the reliability and low latency that modern analytical systems demand.
Our process
- Data identification, exploration, and provenance
- Data hygiene models, schema and versioning
- Automated re-runs and timely notification alerts
- Mathematical data transformations leveraging topological and geometric methods
- On-prem or cloud deployments for cleaned data in lakes, warehouse, and lakehouses
Software & Data Engineering
Accelerate your R&D process and transform messy, unstructured data into clean, validated data with our hybrid approach of AI tooling and mathematically grounded analysis. We build and maintain systems that get it from prototype to production.
Data Engineering
Most data engineering lacks mathematical validation, leading to silent failures that compound through ML/analytics workflows. We process your data in the format you already have, whether it’s a cloud warehouse, open-source setup, or neglected data accumulated over the years. We don’t force migrations or rebuild from scratch unless that is the right call.
Our process
- Data identification, exploration, and decision making before design choices are settled
- Incremental improvements through customer iteration
- Deployment, documentation, tests, and potential monitoring so your team can maintain without us
What sets us apart
We are mathematicians and computer scientists who have worked together for 5+ years, published a combined 50+ peer-reviewed research papers, maintain 10+ active open-source projects, and led government-funded research projects.
- Mathematical Depth — We are mathematicians who bring rigorous theory, not just off-the-shelf models, to every engagement. We have published a combined 50+ peer-reviewd papers on topological data analysis, graph theory, machine learning, and AI.
- Interpretability by Design — We prioritize methods that can be explained and validated, so your stakeholders and compliance teams understand what the system is doing and why.
- Domain-Adaptive Solutions — We don't apply generic pipelines. Each solution is tailored to the structure of your data, your operational constraints, and your decision environment.
- End-to-End Ownership — From raw data ingestion to deployed models, we cover the full stack so nothing falls through the cracks between teams.
- Trusted in High-Stakes Contexts — Our scientists have led projects funded by NOAA, USFS, and NSF. We work in environments where errors carry real consequences.
Our work in action
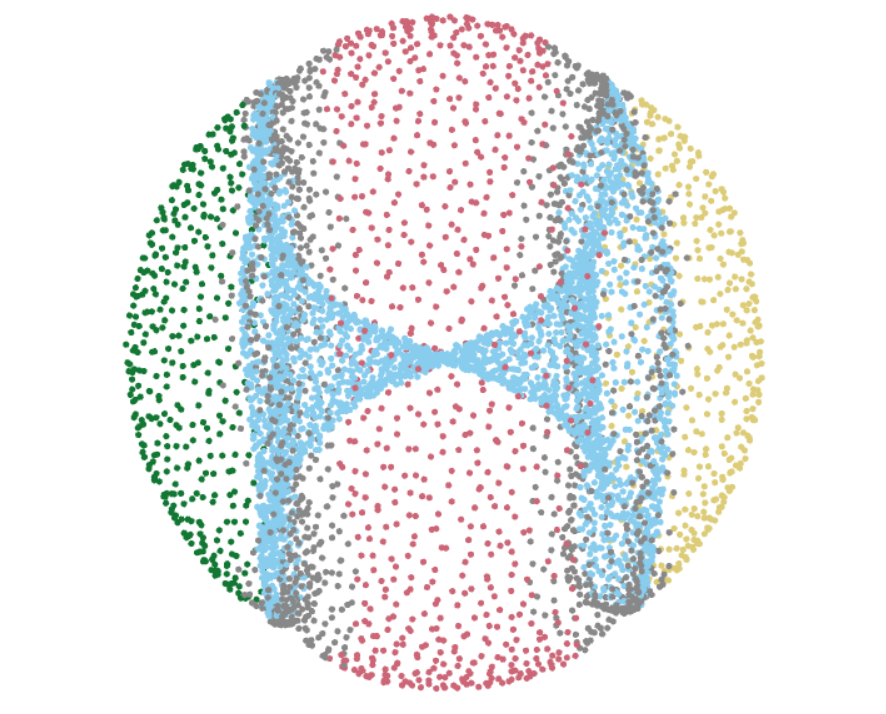
Dimension estimation and stratification finding for point clouds
Dimmer estimates the local dimension of point cloud data and recovers its stratification — a partition into locally consistent, lower-dimensional pieces — revealing structure that single-number dimension estimates miss.
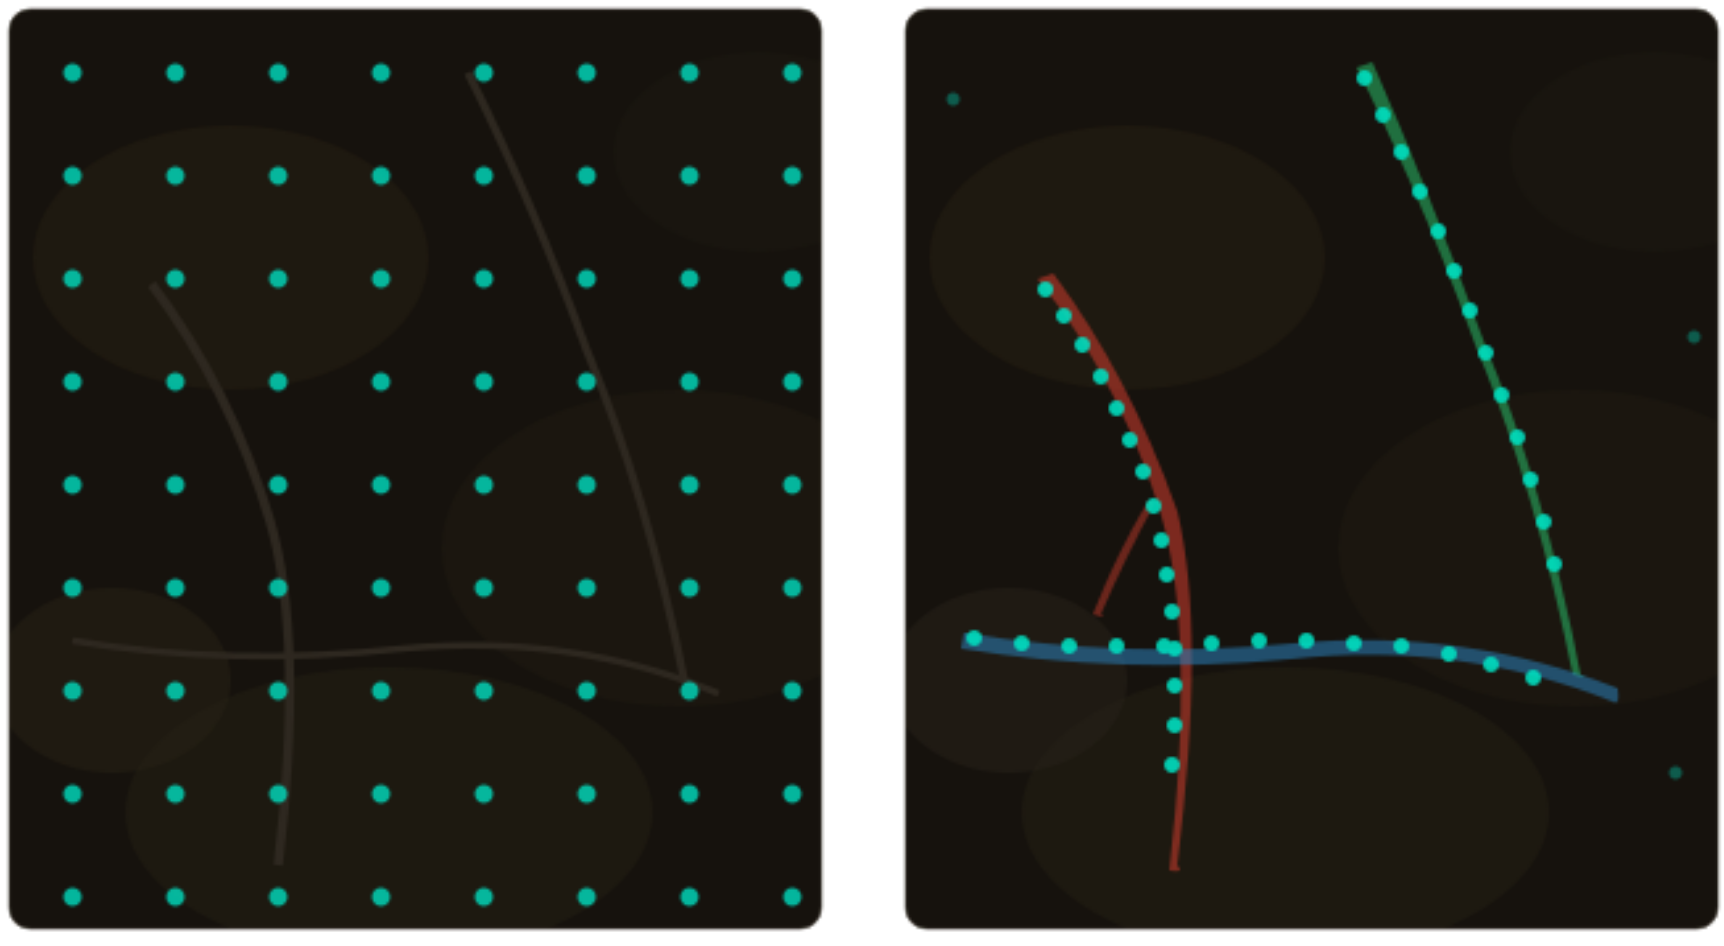
Automating ridgeline identification where labelled data falls short
Geomprompt is a geometry-driven approach to prompt enhancement that detects ridge-like features and guides SAM without task-specific training data, capturing the majority of relevant segments at a fraction of the prompt density of standard approaches.
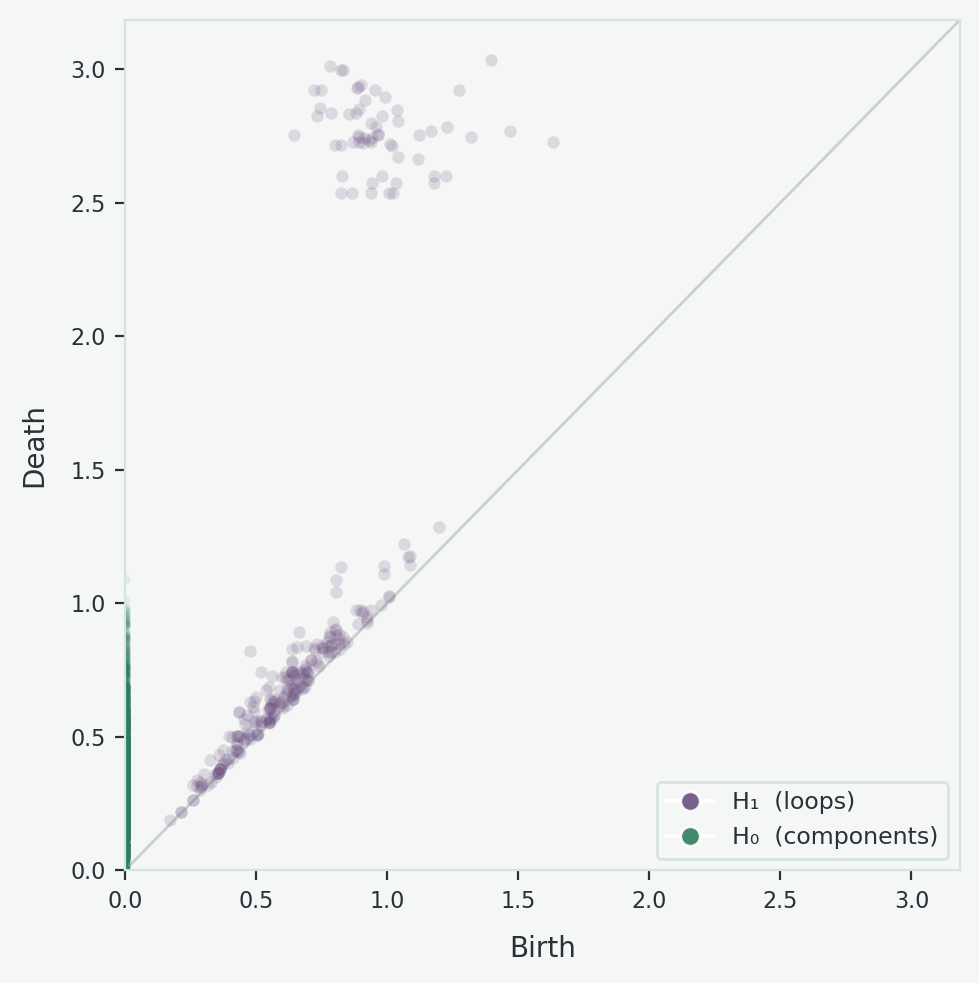
Distributed Persistent Homology
Dispers provides a simple interface to Distributed Persistent Homology.
Contact us
Have a question or want to work with us? Send us a message and we'll get back to you.